I am a PhD student in the Machine Learning Systems CDT at the University of Edinburgh, supervised by Laura Sevilla-Lara and Oisin Mac Aodha. Before Edinburgh, I received my M.Eng. from the Institute of Automation, Chinese Academy of Sciences, advised by Dong-Ming Yan and Weize Quan, and my B.Eng. in Computer Science from the University of Chinese Academy of Sciences.
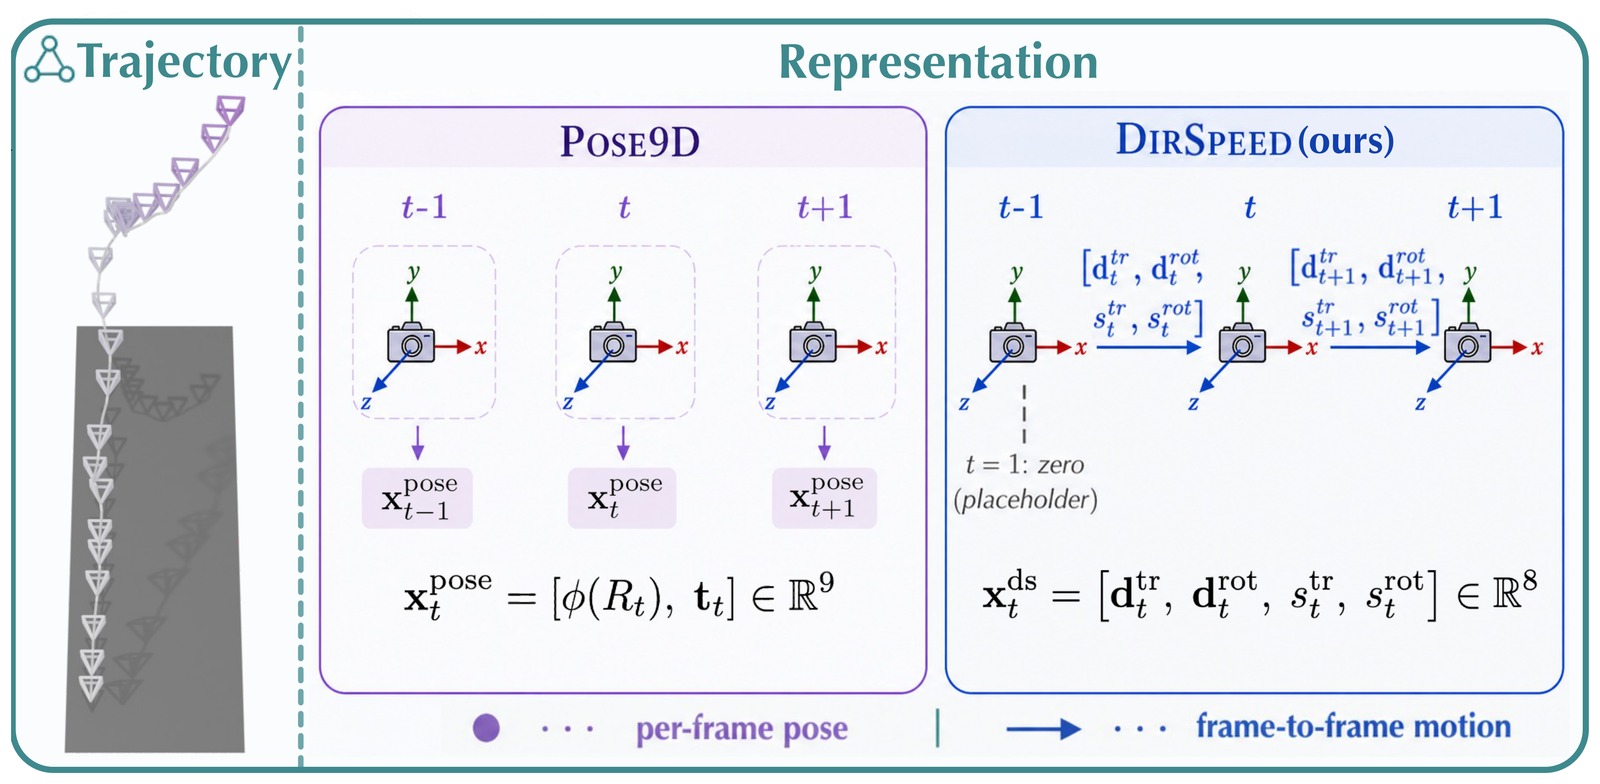
My research is about how visual models represent the physical structure of the world, and how that structure can be made controllable. I currently focus on camera motion in video, and more broadly on whether such structure already emerges inside large pretrained models and can be reused across understanding, prediction and generation.
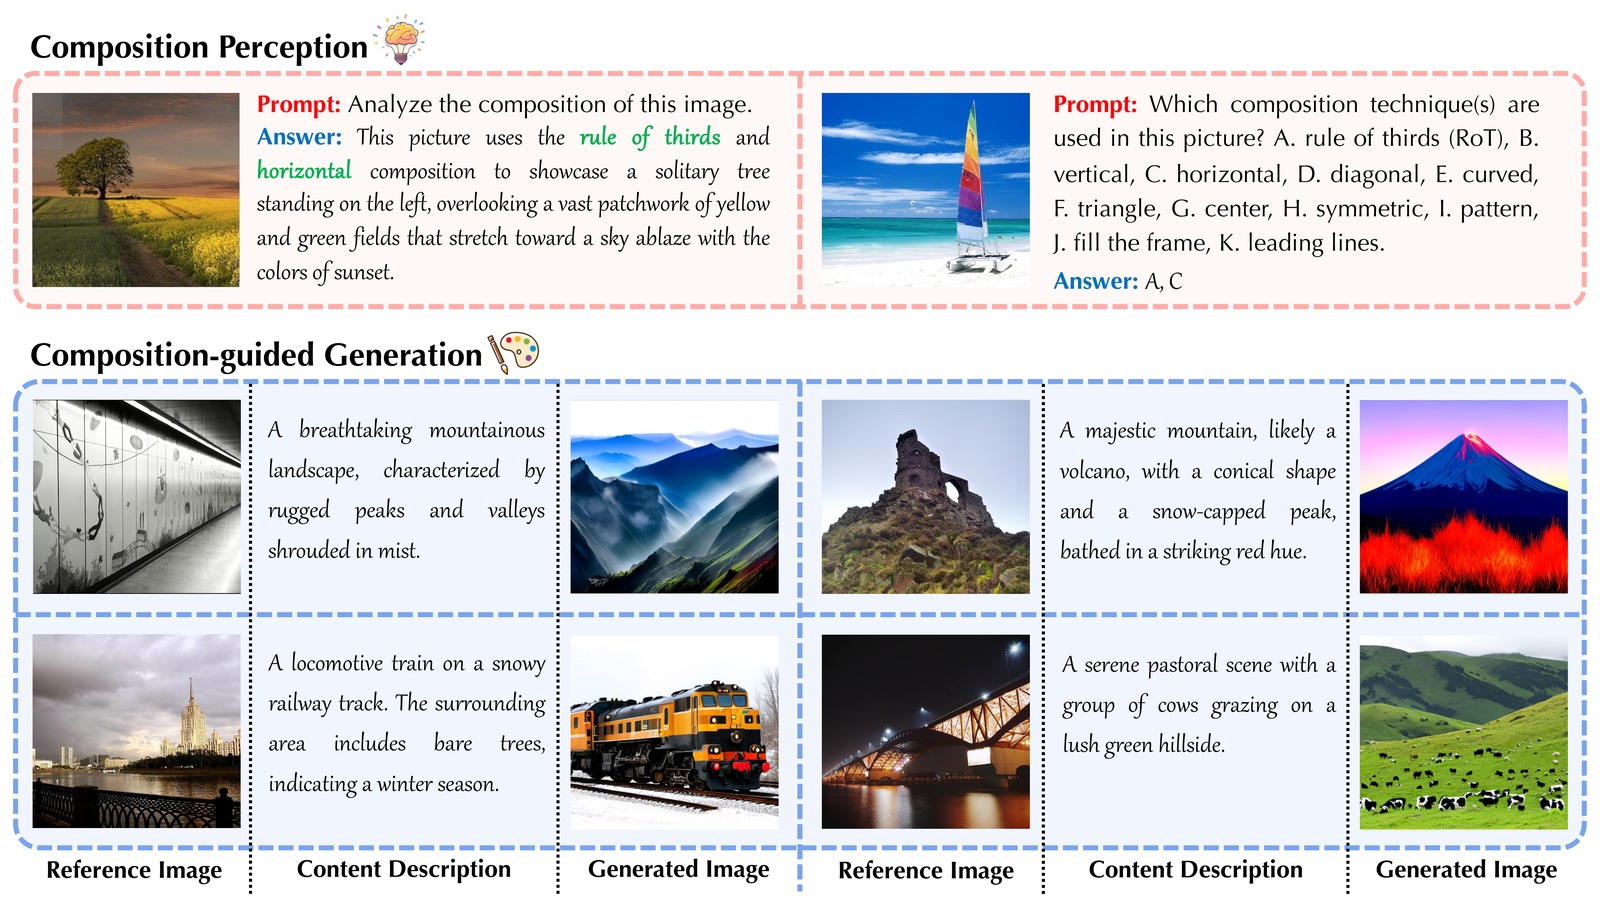
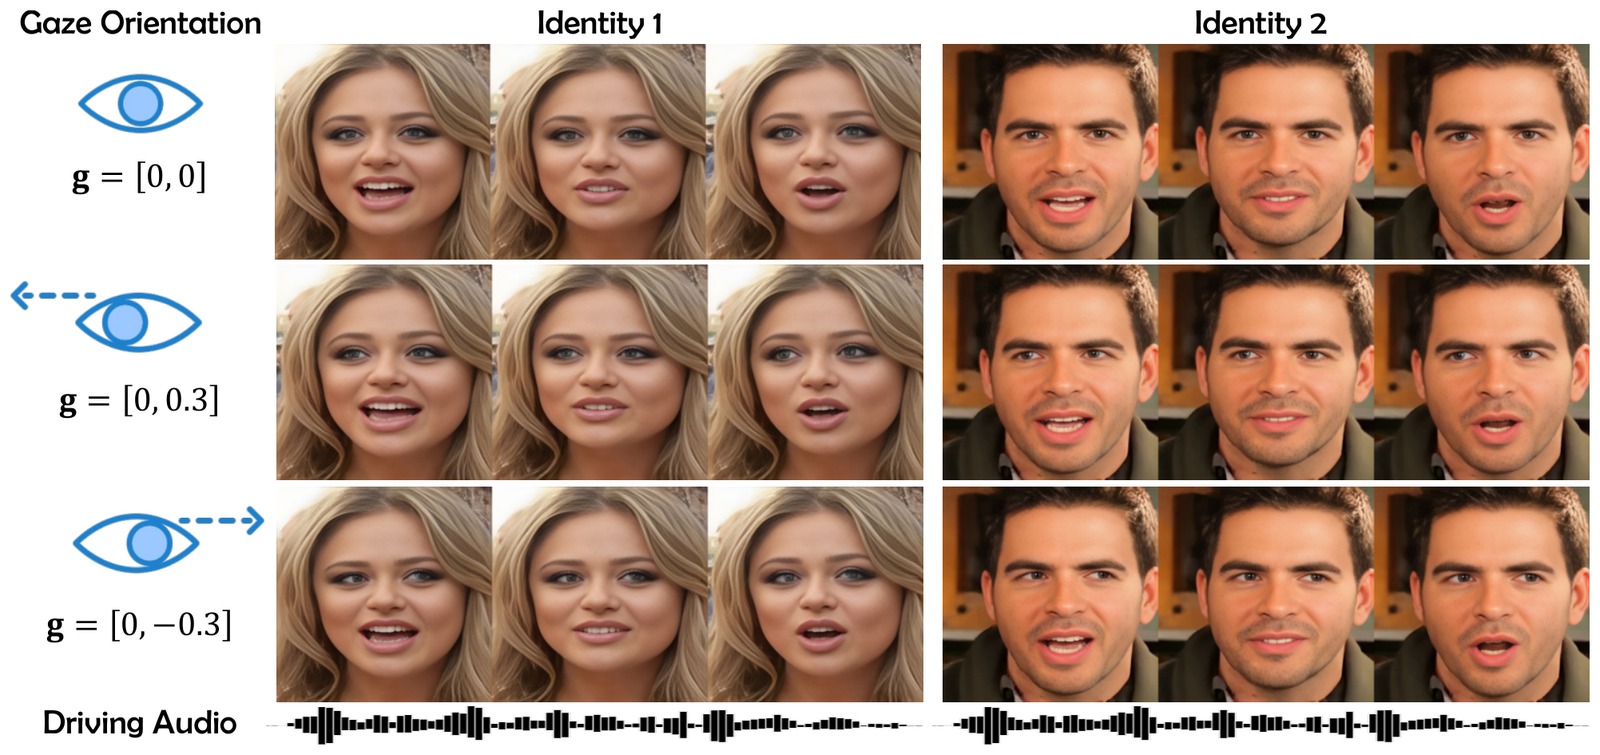
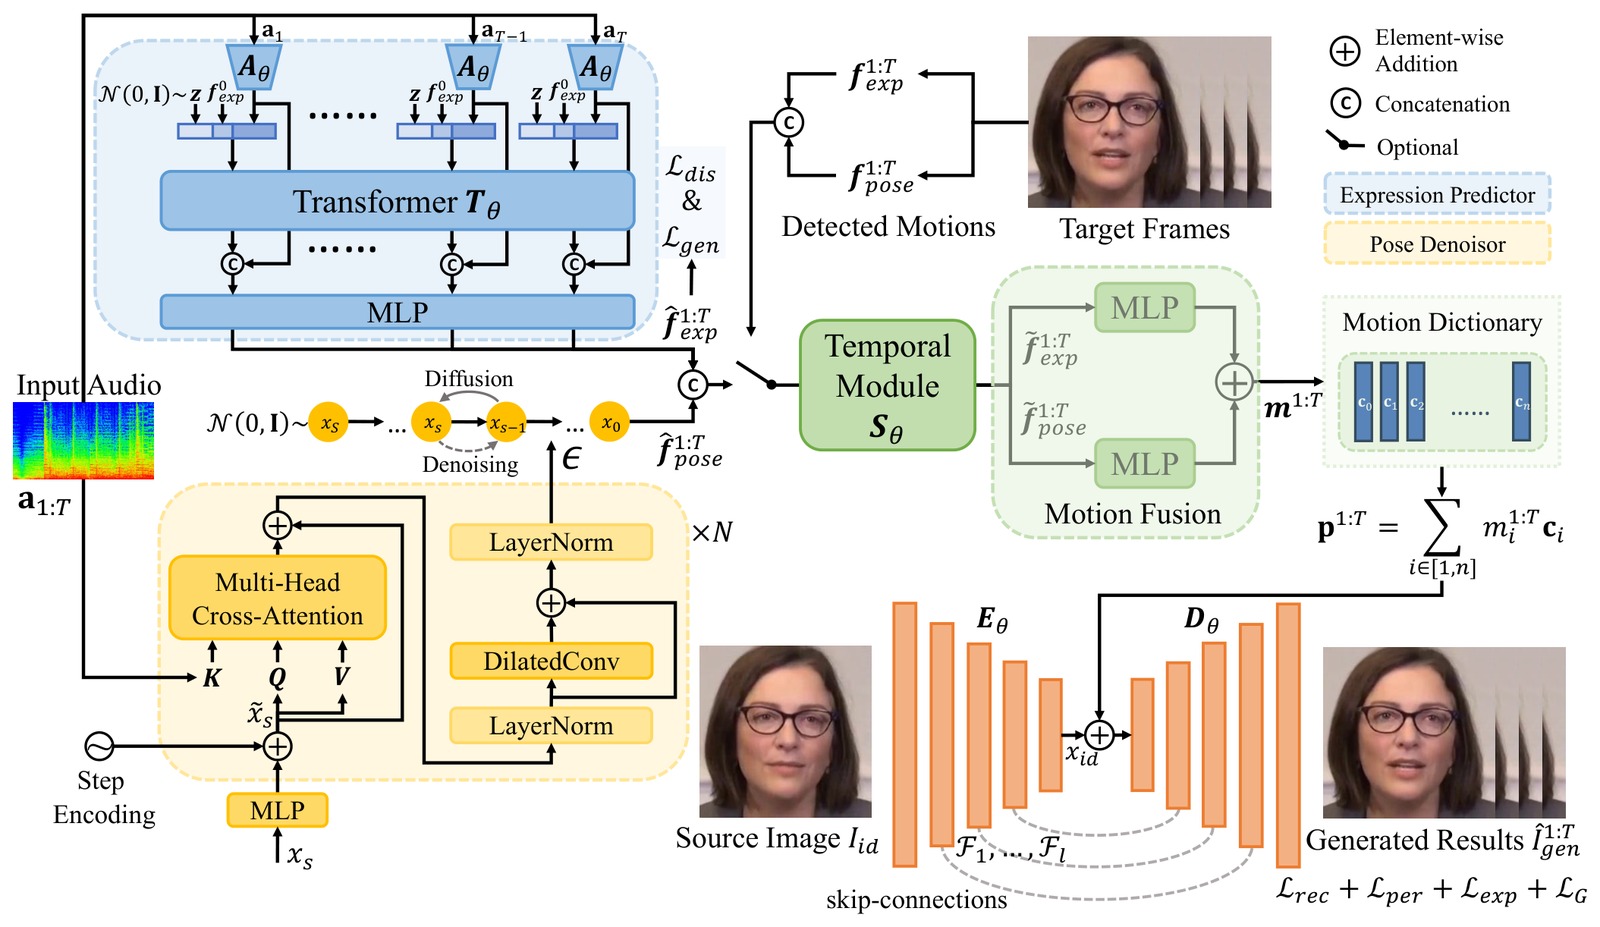
Earlier I worked on data-driven inverse problems in geometry processing, audio-driven talking-face generation, and composition-aware unified multimodal models — different problems, one question: what a model should represent explicitly, and what it should be left to infer.
I am open to research internship opportunities — feel free to get in touch.
News
- 2026.09Two papers accepted to NeurIPS 2026.
- 2026.06One paper accepted to ECCV 2026.
- 2025.09Started my PhD at the University of Edinburgh.
- 2024.12Two papers accepted to AAAI 2025 and ICASSP 2025.
- 2024.03One paper accepted to IEEE TVCG.
Publications
Experience